

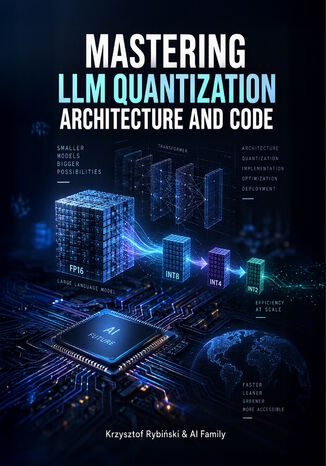
Mastering LLM Quantization: Architecture and Code. From Quantization Mathematics to CUDA, Triton, Inference Runtimes, and Production Optimization Krzysztof Rybiński
 angielski
- Autor:
- Krzysztof Rybiński
- Wydawnictwo:
- Packt Publishing
- Ocena:
- Stron:
- 446
- Dostępne formaty:
-
PDFePub
Opis
książki
:
Mastering LLM Quantization: Architecture and Code. From Quantization Mathematics to CUDA, Triton, Inference Runtimes, and Production Optimization
The book begins with quantization basics, numerical representations, error analysis, calibration, scaling, and sub-byte math. Readers explore GPTQ, AWQ, SmoothQuant, QLoRA, quantization-aware training, FP8, and other low-bit techniques. Implementation sections connect mathematical methods with real GPU systems, covering CUDA kernel engineering, Triton, CUTLASS, memory layouts, tensor operations, kernel optimization, and hardware-aware performance analysis. It also covers activation and KV-cache quantization, memory management, batching, and techniques for reducing inference cost while preserving model quality.
Practical deployment chapters examine GGUF, vLLM, TensorRT-LLM, ONNX Runtime, and other inference environments, showing how quantized models move into production systems. Hardware profiling, benchmarking, precision trade-offs, throughput, latency, memory consumption, and deployment optimization are treated as practical engineering problems. The result is an end-to-end perspective connecting quantization mathematics, algorithms, GPU architecture, optimized kernels, inference runtimes, and production deployment.

 Wybrane elementy graficzne tej sekcji powstały przy wsparciu AI
Szczegóły książki
- Tytuł oryginału:
- Mastering LLM Quantization: Architecture and Code. From Quantization Mathematics to CUDA, Triton, Inference Runtimes, and Production Optimization
- ISBN Ebooka:
- 978-18-088-2160-8, 9781808821608
- Data wydania ebooka :
-
2026-11-27
 Data wydania ebooka często jest dniem wprowadzenia tytułu do sprzedaży i może nie być równoznaczna
z datą wydania książki papierowej. Dodatkowe informacje możesz znaleźć w darmowym fragmencie.
Jeśli masz wątpliwości skontaktuj się z nami [email protected].
- Język publikacji:
- angielski
- Rozmiar pliku Pdf:
- 948.8kB
- Rozmiar pliku ePub:
- 78.8kB
Dzięki opcji "Druk na żądanie" do sprzedaży wracają tytuły Grupy Helion, które cieszyły sie dużym zainteresowaniem, a których nakład został wyprzedany.
Dla naszych Czytelników wydrukowaliśmy dodatkową pulę egzemplarzy w technice druku cyfrowego.
Co powinieneś wiedzieć o usłudze "Druk na żądanie":
- usługa obejmuje tylko widoczną poniżej listę tytułów, którą na bieżąco aktualizujemy;
- cena książki może być wyższa od początkowej ceny detalicznej, co jest spowodowane kosztami druku cyfrowego (wyższymi niż koszty tradycyjnego druku offsetowego). Obowiązująca cena jest zawsze podawana na stronie WWW książki;
- zawartość książki wraz z dodatkami (płyta CD, DVD) odpowiada jej pierwotnemu wydaniu i jest w pełni komplementarna;
- usługa nie obejmuje książek w kolorze.
Masz pytanie o konkretny tytuł? Napisz do nas: [email protected]
Książka drukowana

Oceny i opinie klientów: Mastering LLM Quantization: Architecture and Code. From Quantization Mathematics to CUDA, Triton, Inference Runtimes, and Production Optimization Krzysztof Rybiński
(0)